相似不代表相關
傳統切塊搜尋容易找到語意相近的文字,卻可能失去章節關係、前後條件與完整證據。對大型技術文件來說,結構本身就是資訊。
PageIndex 的做法
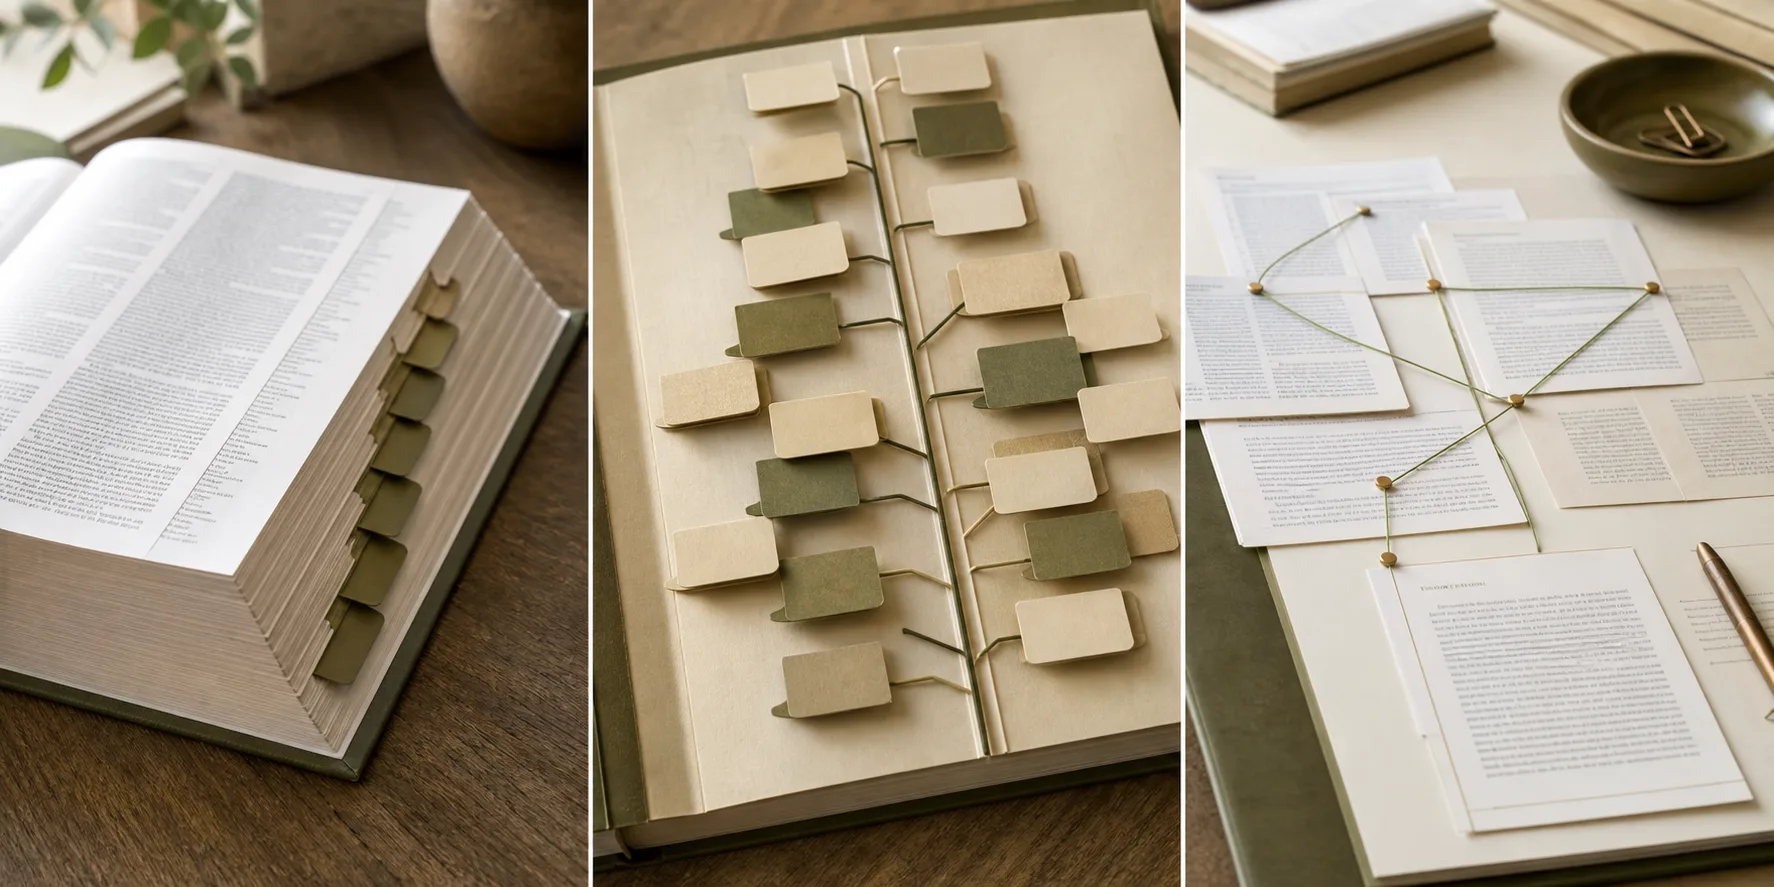
PageIndex 保留文件的樹狀章節,讓 LLM 先判斷應該走到哪一個分支,再找出真正相關的頁面。這比先切成大量 chunks 更接近人閱讀長文件的方法。
搭配受控的知識循環
再用 Wiki 累積經過驗證的摘要、概念和交叉連結,搜尋就不只是一次性回答,而能逐步形成可追溯的知識。
Similarity Is Not Relevance
Chunk search can find semantically similar text while losing chapter relationships, conditions, and evidence. In technical documents, structure is information.
How PageIndex Works
PageIndex preserves a chapter tree. The LLM first decides which branch to follow, then retrieves the relevant pages. This resembles how people navigate long documents.
A Controlled Knowledge Loop
A wiki can accumulate reviewed summaries, concepts, and links. Retrieval then becomes traceable knowledge rather than a one-off answer.